There is a problem with the attention we have just built, and it is a serious one. As it stands, every token can look at every other token — including the ones that come after it. For reading a finished sentence that is perfectly fine. But a language model does not read; it generates, and generation comes with an iron rule: when predicting the token at position , the model may use positions through and must not see position or anything beyond. Break that rule and the model is being shown the answer it is supposed to be predicting, which teaches it precisely nothing.
Enforcing "look back, never forward" is the job of causal masking, and it is what makes the attention in a language model causal (also called masked self-attention).
The problem in one picture
Recall the score table: entry is how much token attends to token . "Token may not look ahead" means every entry where — the whole region above the diagonal — must be forbidden. Token 1 may attend only to token 1; token 2 to tokens 1–2; and so on. The allowed region is a lower triangle.
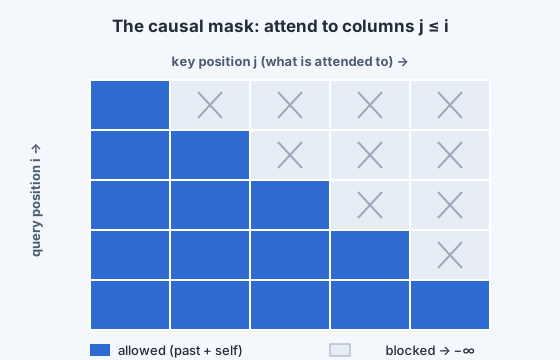
How the mask works
We cannot just delete the forbidden entries — the softmax needs a full row. Instead we set each forbidden score to negative infinity before the softmax:
Why ? Because softmax exponentiates, and . A masked position therefore receives exactly zero attention weight, and the remaining (allowed) weights still sum to 1 among themselves. In practice a very large negative number stands in for , but the effect is the same: the future contributes nothing, and each token's output is a blend of itself and its past only.
The payoff: train on every position at once
Masking is not just a correctness patch — it is what makes training efficient. Feed in a sentence of tokens. With the causal mask in place, in a single forward pass the model produces a next-token prediction at every position simultaneously:
- position 1 predicts token 2 (having seen only token 1),
- position 2 predicts token 3 (having seen tokens 1–2),
- …
- position predicts token (having seen tokens 1 to ).
Each of these predictions is made without any leak from the future, because the mask guarantees it. So one sentence gives supervised prediction problems at once, all trained together with the ordinary cross-entropy loss. This parallel, leak-free training over every position is a large part of why transformers train so efficiently.
During training the full target sentence is present, and the mask is what stops each position from seeing its own answer — so all positions train in parallel. During generation the future genuinely does not exist yet; the model produces one token, appends it, and runs again. The mask makes the two settings behave identically, which is exactly why a model trained this way can generate correctly.
Where this leaves us
We now have the complete attention operation used in a language model: project to queries, keys and values; score and scale; mask the future; softmax; blend the values. One such operation is a single attention head. The next module asks an obvious question — if one head learns one kind of relationship, why not run several in parallel? — and arrives at multi-head attention.
Toggle the mask and see the future positions disappear from every row.